 AIpresso
Hi there, this is your daily ☕️ AIpresso.
In today's AIpresso:
🔌 DeepSeek adds chat-to-plugin builder to its app
🔐 Anthropic open-sources tool to verify AI responses
⚡ New chat threads make Claude 35% faster on long conversations
🐱 Meituan debuts 1.6T-parameter multimodal AI model
🧠 MIT edits Qwen's weights to 6x its math score
Plus: 💡 5 strategies & tactics, 🎁 8 more stories you might like, 🧰 6 tools, and 📚 5 papers.
From our partner
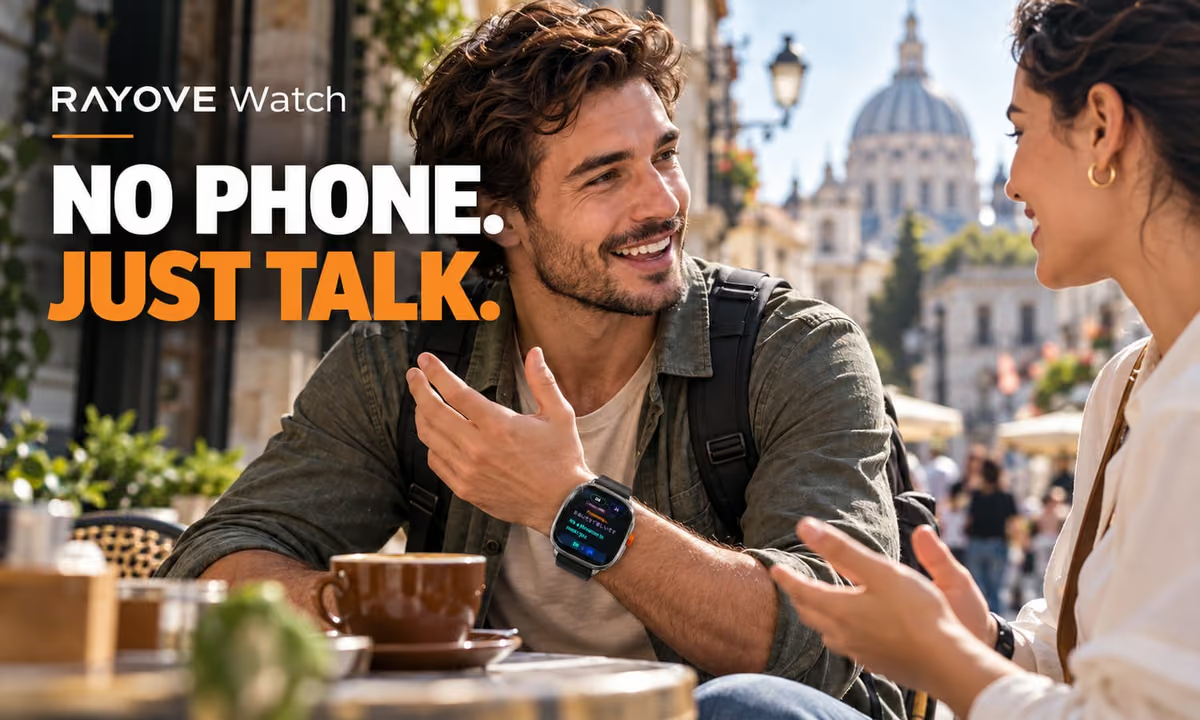
RAYOVE Watch is a hands-free AI translation smartwatch built for real conversations.
Speak naturally and hear the translation from your wrist in under a second, with online support for 73 languages.
Point the camera at menus, signs or printed text for OCR translation.
No need to keep reaching for your phone.
RAYOVE Watch is now live on Kickstarter.
DeepSeek adds chat-to-plugin builder to its app LINK
- DeepSeek has added a Creator Mode to its DeepSeek Harness app, letting users build custom plugins by describing them in plain English, part of the Hangzhou company's push into AI agent tooling.
- Published demo prompts build things like a sidebar rendering 3D models of the Eiffel Tower and Great Wall, an interactive Transformer-computation game, a dark-themed video editing workbench driven by natural-language requests, a paper reader, and a token-usage statistics panel.
- DeepSeek also shipped a research prototype, dsh-superagent, that works on GitHub repos under host-enforced allow-lists, though DeepSeek warns some demo plugins took several rounds of conversation, so a single prompt may not reproduce the video exactly.
Anthropic open-sources tool to verify AI responses LINK
- Anthropic open-sourced FlashProve, a research prototype that uses zkSNARKs to cryptographically prove a language-model reply came from a provider's committed weights without exposing them, hitting 110 tokens/sec of proof generation on Llama 4 Maverick.
- The software-only design exploits Maverick's mixture-of-experts so prover work scales with the ~17B active parameters per token rather than all 400B, fitting on a single 80GB GPU while hiding which experts ran.
- Verification runs CPU-only in about 17 seconds against a ~6.5MB commitment, but proving cost ran roughly 72x the per-GPU time of FP8 vLLM inference, and the Apache 2.0 release is an unmaintained artifact capped at 1,024-token contexts with no independent security audit.
New chat threads make Claude 35% faster on long conversations LINK
- Anthropic launched Message Threads in public beta on Claude, which only transmits what's changed since the last message instead of resending the full conversation, cutting time to first token by about 35% on large requests.
- The speedup applies to requests between 500,000 and one million tokens, with coding agents, computer-use agents, and document- or image-heavy workflows benefiting most, and threads staying encrypted in memory between calls.
- It works on the Claude platform plus AWS, Microsoft Foundry, and Google Cloud, though token usage stays the same since Claude still reads the entire history, and threads expire after five minutes of inactivity.
Meituan debuts 1.6T-parameter multimodal AI model LINK
- Meituan released LongCat 2.5, a 1.6T-parameter multimodal model combining native visual understanding with coding and multi-step tool use for agents operating across complex codebases and full-project builds, now live on AI Gateway.
- It accepts text and image inputs with a 1M-token context window, targeting visual programming, creative design, 3D tasks, and longer agent workflows that span planning through execution across code, documents, and extended task histories.
- Pull it via meituan/longcat-2.5 in Claude Code, Codex, or Cursor after installing the latest Vercel CLI, with AI Gateway reflecting provider pricing at no markup and no platform fee on inference, including BYOK requests.
MIT edits Qwen's weights to 6x its math score LINK
- MIT CSAIL researchers used GPT-6 Astra to directly edit Qwen3.5-0.8B's weights and lift its MATH-500 score from 7.9% to 48.1%, with no gradient descent or retraining.
- Astra traced the model's reasoning loops to layers 15 and 19, subtracting one direction across 131,072 weights, just 0.016% of the model, with GSM8K rising to 67.1% and the share of answers hitting the token limit dropping from 93% to 33.1%.
- The method diagnoses and patches small models rather than adding skill: the authors report it failed to move Gemma 3 270M, which rarely loops, by more than a point, and note the results are unreplicated and limited by context length.
Strategies & Tactics
> Scaling Git at OpenAI: OpenAI rebuilt the backend that stores its code so many engineers and AI agents can save and fetch changes simultaneously, cutting typical save delays nearly fivefold.
> Transformers Model Integration Contracts: Catch model bugs on code reviews by testing shrunk CPU versions of real models against recorded correct outputs, flagging regressions before they reach the main codebase.
> Diagnose Distributed AI Workload Failures with NVIDIA Attribution: Trace a distributed AI training failure back to its true root cause by correlating logs and hardware events, separating the original fault from its cascading downstream symptoms.
> Nine engineers, 1,211 code updates in a day: Lessons from building Copilot Cowork: Let a small team ship far more code by having agents write most of it within strict human-set rules for specs, review, and security.
> Building Legal Agents When You Can't See the Data - Jacob Lauritzen, CTO of Legora: Legora builds client-confidential legal agents by testing them in simulated case environments and analyzing paraphrased activity logs, since privacy bars seeing real client data.
Other news you might like
- Nvidia pushes cloud customers to cut back on China business LINK
- Reading Anthropic's S-1 - Merge Conflict, by Tilo Mitra LINK
- Salesforce to acquire Cresta in deal reportedly valued at $2.7bn LINK
- CrowdStrike unveils a kill switch for AI agents that escape human control LINK
- Open models can do 90 percent of agentic work at a twentieth of the cost of a frontier LLM: Gartner LINK
- Anthropic prepares to release Claude Mythos 5.5 model LINK
- GPT-Rosalind-6 System Card Addendum LINK
- LifeVal LINK
Trending tools
Viggle JST-2: physics-aware model that generates 3D characters and scenes from text or images with motion built in, skipping separate rigging and skinning steps. LINK
Hob: free, open-source AI app running local models to read and edit files, build charts, fill PDFs, and search entirely offline. LINK
Intrascope 2.0: combines multiple AI models, company knowledge, and agentic workflows in one workspace, with model routing, RAG, and admin budget and access controls. LINK
Basedash: an AI-native business intelligence platform that builds dashboards from plain language, connecting your data and generating visualizations without writing SQL. LINK
Agent Handshake by Fini: AI support agent for regulated industries that resolves tickets across voice, chat, and email, flagging knowledge gaps and escalating to humans when needed. LINK
OpenAgentCore: an open-source, self-hosted implementation of the OpenAI Agents API that runs coding agents on your own machines and models. LINK
Trending papers & reports
A rounding bug in AI training silently throws away most of the small tweaks a model learns each step, and a one-line fix recovers them, boosting results by ~6 points at near-zero cost. LINK
AI sabotage detectors score high on the standard test mostly by spotting writing-style giveaways, with dead-simple shortcuts outranking 20 of 24 safety monitors, meaning top scores don't prove a model catches malicious code. LINK
Model looping, a trick that reuses layers to make a trained AI smarter without adding size, only pays off for the smallest models and backfires at scale, running up to ~13 points worse than cheaper alternatives. LINK
Diffusion model conversion turns existing text models like Llama and Gemma into faster parallel-generating versions using a cheap add-on, in under 4 hours on one free cloud GPU, without retraining the original. LINK
Expert pruning cuts the number of specialized sub-models a large language model stores, keeping just 50% to 75% while preserving accuracy, slashing the memory needed to run these models in production. LINK
See you tomorrow for a new dose of ☕️ AIpresso!