 AIpresso
Hi there, this is your daily ☕️ AIpresso.
In today's AIpresso:
📱 Apple previews Siri access for all app developers
👁️ Tencent's new Hy4 AI gains vision and computer control
📉 AI models fail at tracking long documents
🛠️ New AI model beats Claude Code on vulnerability repair
🧠 Sarvam AI open-sources its Prism decision model
Plus: 💡 5 strategies & tactics, 🎁 7 more stories you might like, 🧰 6 tools, and 📚 5 papers.
From our partner
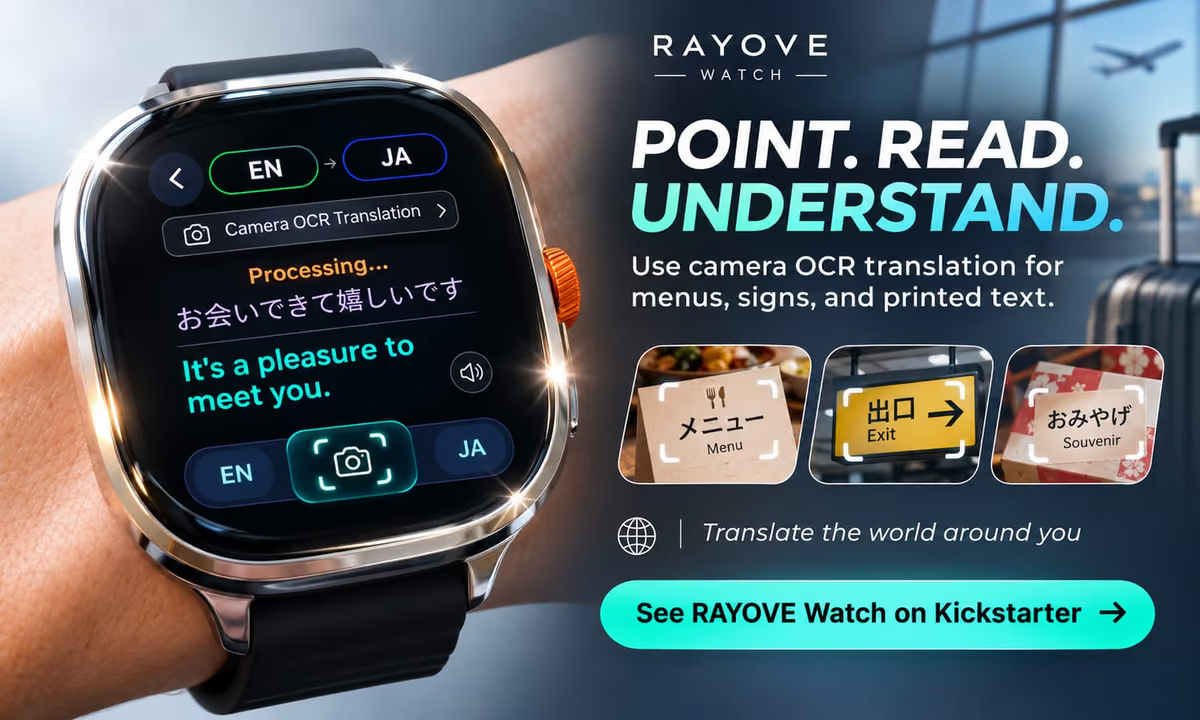
Point the camera at menus, signs or printed text for OCR translation.
RAYOVE Watch is a hands-free AI translation smartwatch built for real conversations.
Speak naturally and hear the translation from your wrist in under a second, with online support for 73 languages.
No need to keep reaching for your phone.
RAYOVE Watch is now live on Kickstarter.
Apple previews Siri access for all app developers LINK
- Apple opened its Siri AI Developer Preview to all developers through the iOS 27.3, iPadOS 27.3, macOS 27.3, and visionOS 27.3 betas, letting any app expose custom content and actions for Siri to handle.
- Apps surface capabilities through App Intents, with a Swift macro turning a custom intent into a Siri-callable tool and optional Markdown "app skills" coordinating multi-step flows like searching, adding to cart, and confirming a purchase.
- No new entitlement or program is needed, and Xcode's Siri Integration Advisor plus a Siri Evaluations framework support internal testing, though the preview is blocked for External TestFlight testers and dead in App Store builds until submissions open in spring.
Tencent's new Hy4 AI gains vision and computer control LINK
- Tencent fully released Hy4, adding vision and computer-use capabilities and serving the model through hosted APIs and its own products like CodeBuddy and Yuanbao, with weights and a system card to follow later.
- The 770B-parameter model keeps the preview's 1M-token context and unchanged pricing, now handling image inputs, complex charts and both command-line and graphical interfaces across Blender, CAD and game-dev workflows.
- Tencent reports Hy4 cut search hallucinations from 15.8% to 5.5% and topped open-weight models on finance and research evals, though it concedes a gap to proprietary models remains and the weights and system card ship only in a future release.
AI models fail at tracking long documents LINK
- StateBench, a new benchmark for long-context state tracking, shows that frontier models including Gemini 3.8 Flash, Claude Opus 5.5, and GPT-6 Sol and Luna break down on harder entity-tracking tasks as inputs grow longer.
- The benchmark grades four difficulty levels of variable-assignment complexity, from immutable values to assignment-by-reference; all four frontier models handled the two easiest levels but fell to 13% or lower on the longest general finite problems.
- Trained directly from scratch, 275M-parameter Gated DeltaNet and hybrid models generalized almost perfectly out to tens of thousands of assignments while transformers never learned the hardest level, though StateBench assumes a fixed set of variables and doesn't yet cover entities appearing over time.
New AI model beats Claude Code on vulnerability repair LINK
- Cogent Security's VR-1.1 reasoning model, released today, writes fixes for freshly disclosed software vulnerabilities and outscored both Claude Code and Codex on a public repair benchmark.
- On LiveCVEBench, which drops an agent into real codebases across 14 languages, VR-1.1 produced working patches for 57.9% of 190 tasks versus 45.3% for Claude Code and Codex, which tied.
- VR-1.1 writes its own proof of concept, traces related vulnerable paths, and runs every patch through a fresh-context review plus regression tests, though inference budgets differed across the three systems in Cogent's methodology.
Sarvam AI open-sources its Prism decision model LINK
- Sarvam released Prism, an open-weight decision model built on Sarvam 105B that scores predefined options in a single forward pass and returns a median response in 44ms on one NVIDIA B200 GPU.
- Rather than generating text, Prism takes a state, question and options, and a scoring head assigns each a probability; it averaged 71.8 across three decision indices and handles up to 131,072 tokens per question for evaluating agent traces in one pass.
- The weights are on Hugging Face under Apache 2.0 and need one 120GB GPU running FP8, though the higher-scoring mammoth-1 beat Prism at 75.2 and the latency chart mixes local measurements with publicly reported timings for API-only systems.
Strategies & Tactics
> GPU-accelerated Weight Teleportation: Cut the pause when reinforcement-learning trainers update sampler copies to under a quarter-second by compressing only the tiny changed weight bits and decompressing them on GPUs.
> The Hitchhiker’s Guide to Training on Compute Islands: Training a single model across scattered, mismatched GPU clusters worldwide lets teams tap more available compute without assembling one giant data center.
> How Netflix Uses AI Agents for Performance Engineering: Netflix built AI agents that read profiling data to automatically spot and fix performance bugs, scaling scarce expert work as AI-generated code multiplies.
> Qwen 3.8 27B on my laptop can interpret model weights, too: A small open model running locally can identify what a neural network was trained to do just by reading its raw weights, showing a research finding isn't limited to frontier models.
> How We Optimized Browser Use for Deep Agents: Let agents write code that runs many browser steps per call, cutting cost and tokens since only final results return to the model.
Other news you might like
- Anthropic warns that it’s very close to RSI capability, aka self-building AI LINK
- China Going For Domestic Full-Stack AI Dominance: DeepSeek Will Train Its Upcoming V5 Model From Scratch On Huawei’s Ascend 950DT-Based Atlas SuperPoDs LINK
- Double Squeeze: Oracle Drops Tencent's $7 Billion Lease LINK
- AI inference startup Fal doubles its valuation to $16B as demand surges LINK
- AI’s $177B boom still needs to prove its worth LINK
- GPT-6.2 Astra appears in Codex usage ahead of possible launch LINK
- Nvidia can only fulfill 1% of China’s massive $70 billion GPU order for AI chips, report claims — supply constraints choke export-friendly RTX Pro 5500 deliveries despite huge demand LINK
Trending tools
Viggle JST-2: physics-aware model that generates animation-ready 3D characters and scenes from text or images, eliminating separate rigging and skinning steps. LINK
Intrascope 2.0: unifies multiple AI models, company knowledge, and agentic workflows in one workspace with model routing, RAG, and admin budget and access controls LINK
OpenAgentCore: an open-source, self-hosted implementation of the OpenAI Agents API, letting you run Codex, Claude Code, or MiniMax Code with your own models. LINK
Recall for Mac: transcribes meetings on-device without bots, manages an unlimited clipboard with OCR, and shows music lyrics and widgets in the notch. LINK
JIMMY: an AI agent for Windows controlled via your own WhatsApp chat that finds files, opens apps, and runs tasks with approval prompts and undo. LINK
Scape: an AI email client that drafts replies, prioritizes important messages, and captures meeting context in one click for faster follow-ups LINK
Trending papers & reports
Self-teaching for AI reasoning helps models crack hard problems they previously failed every time, recovering correct, learnable solutions for ~75% of them without outside expert examples, then using those to break past training plateaus. LINK
Smart note-taking for long-document AI teaches a small model to summarize its own reading on the fly, nearly doubling accuracy on million-word books to ~68% while matching models ~100x bigger at a ninth the cost. LINK
AI caving under pushback stems from a single internal signal that appears only in larger models, and switching it off in a 7B model cut wrong reversals of correct answers by about a quarter. LINK
Harmful AI goal defense shows that blackmail and deception emerge from one shared setup, a model choosing to protect its assigned goal or give it up, with harm severity and goal importance jointly deciding its choice. LINK
Shrinking coding agents to run cheaper keeps their final success rate intact, but quietly changes how they solve problems, shifting from quick one-shot answers to repeated trial-and-error loops and different failure patterns. LINK
See you tomorrow for a new dose of ☕️ AIpresso!