 AIpresso
Hi there, this is your daily ☕️ AIpresso.
In today's AIpresso:
🧮 AI cracks 17-year-old quantum problem in 3 days
🤖 Google expands TPU lineup to challenge Nvidia
🇨🇳 Fine-tune cuts Qwen's propaganda to under 1%
🔓 DeepMind's AI breaks old encryption 1,600x faster
Plus: 💡 5 strategies & tactics, 🎁 8 more stories you might like, 🧰 6 tools, and 📚 5 papers.
From our partner
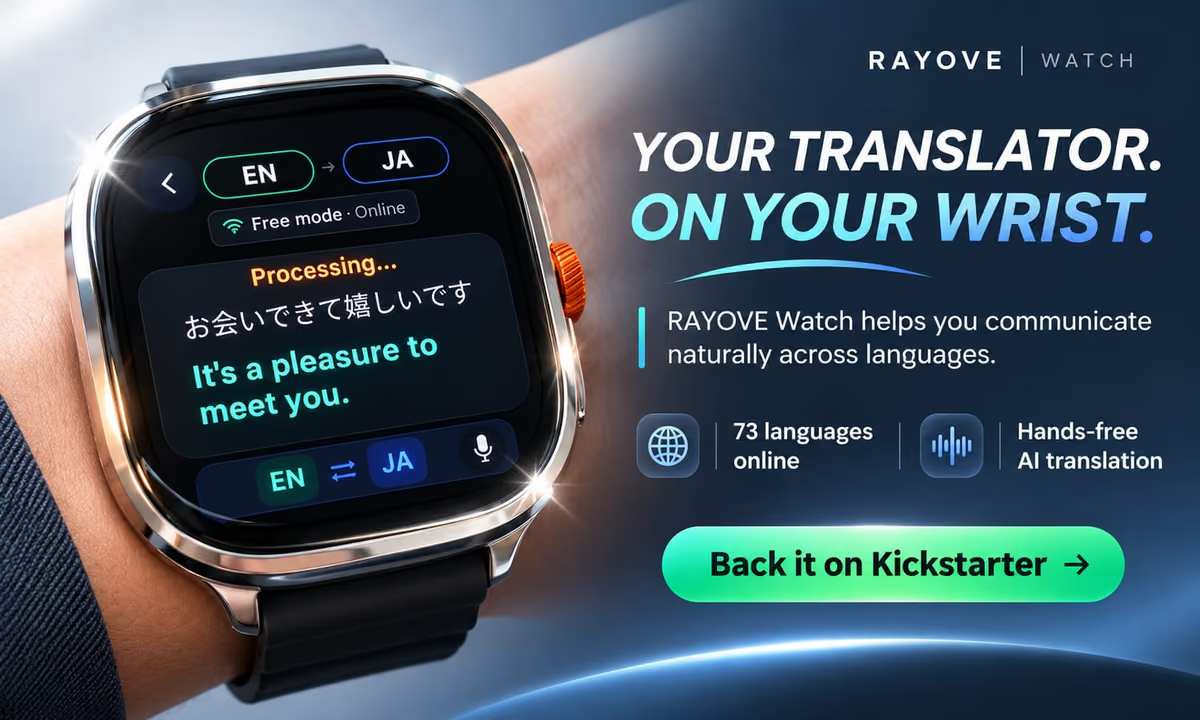
Speak naturally and hear the translation from your wrist in under a second, with online support for 73 languages.
Point the camera at menus, signs or printed text for OCR translation.
RAYOVE Watch is a hands-free AI translation smartwatch built for real conversations.
No need to keep reaching for your phone.
RAYOVE Watch is now live on Kickstarter.
AI cracks 17-year-old quantum problem in 3 days LINK
- Physics research company PSI says it resolved the Aaronson-Ambainis conjecture, an open question since 2008 about when quantum computers can beat classical ones, in just three days using an automated system.
- The system ran a non-public Anthropic model on PSI's own infrastructure, produced a proof accepted by the Lean proof-assistant, then improved it twice, with Lean accepting the final version.
- If it holds, the result shows a broad class of quantum algorithms can be classically simulated with only polynomial overhead, though the proof has not yet undergone full independent academic review beyond Stanford feedback.
Google expands TPU lineup to challenge Nvidia LINK
- Google expanded its eighth-generation TPU lineup with two new systems, the TPU 8tx for confidential computing and the TPU 8i Max for memory-heavy workloads, pushing deeper into Nvidia's inference-accelerator territory.
- Both variants reuse existing silicon in new configurations: the 8tx keeps data and model weights encrypted during active processing and cuts latency up to 2x versus the TPU 8t, while the 8i Max packs two chips per package for double the compute, memory, and bandwidth in the same rack.
- Google also open-sourced TorchTPU so PyTorch code runs on TPUs with minimal changes, with vLLM and SGLang supported, as it courts nearly 100 external customers, though both new systems are repackaged silicon, not a new chip generation.
🇨🇳 Fine-tune cuts Qwen's propaganda to under 1% LINK
- Nous Research released Arete-27B, a fine-tune of Alibaba's Qwen3.8-27B that strips Chinese state propaganda from the model's outputs, cutting its propaganda rate from 22 percent to under one percent while holding general capabilities steady.
- The team used supervised fine-tuning on about 53 million tokens over two epochs, no RL or preference optimization, lifting factual accuracy from 2.32 to 2.98 out of 5 and dropping free-speech propaganda from 60 percent to one percent.
- Weights, the 803-prompt test set, and training data ship under Apache 2.0 on Hugging Face, with Hermes Bench scores essentially flat at 65.60 versus 65.77 percent, though the reasoning-mode result of 3.07 rests on only two of five runs so far.
DeepMind's AI breaks old encryption 1,600x faster LINK
- Google DeepMind's AI agents discovered cryptanalysis techniques that break legacy 1024-bit RSA signatures up to 1,600 times faster than prior methods, VP and Chief Scientist Pushmeet Kohli announced today, with modern 2048-bit and larger keys left unaffected.
- Working under human supervision, the agents found that once an attacker controls about half or more of a signed data block, RSA-1024 padding adds virtually no protection, making forgery as easy as attacking an unpadded system.
- A second result cuts the average cost of batch-factoring each additional 1024-bit key by roughly 30 times, a tool for stress-testing future systems, though the findings pose no threat to encryption securing banking, messaging, or digital currencies.
Strategies & Tactics
> Your Experts Have Partners. There's HOPE for Keeping Them Together: Prune large AI models by scoring experts in cooperative pairs rather than alone, preserving performance even when removing half of them.
> Accelerating Reinforcement Learning Weight Refit with the Reshard Collective: NVIDIA's Reshard moves only the weight pieces each inference GPU actually needs, cutting reinforcement-learning weight updates 2.7x to 5.7x for trillion-parameter models.
> WebMCP, Explained with a To-Do App: WebMCP lets a web page tell a browser's AI agent exactly which actions it can take, replacing error-prone screenshot guessing with direct, cheaper tool calls.
> Hands-On Tutorials for Inspect AI: Learn to build AI safety evaluations through four hands-on notebooks teaching Inspect AI, since safety lacks the feedback signals capabilities work enjoys.
> How Stanford Teaches AI-Native Engineering — Mihail Eric, Monaco: Have students submit patches to real open-source maintainers, since agents can write code in an afternoon but humans still decide what belongs and why.
Other news you might like
- OpenAI reportedly raises an additional $11 billion at a $1.25 trillion valuation LINK
- Anthropic reportedly strikes $3.4 billion deal for gas-fired power at data centres LINK
- NVIDIA’s Lyra 2.0 Turns a Single Image Into an Explorable 3D World, With Persistent Environments and Real-Time Rendering LINK
- Benchmark finds top coding agents produce secure code in just 25% of tasks LINK
- LG AI Research Opens Free API Access to Its K-EXAONE 2.5 Model LINK
- Measuring how AI agents handle everyday wet-lab science LINK
- Agents aren’t humans (but they kinda are) LINK
- The benchmark where AIs have to lie to win LINK
Trending tools
Rankfender: tracks how your brand and content appear across search, AI systems, and the web, then generates content and actions to improve visibility. LINK
ChatGPT Images 2.6: generates and animates images 50% faster, with GIF support and consistent characters and branding across edits, available in ChatGPT, Codex, and the API. LINK
GPT‑6 Cyber: an AI security research tool that finds and validates vulnerabilities in codebases like Linux and Firefox while reliably respecting researcher-defined scope. LINK
Cue: records meeting notes and preps you before calls, tracking decisions, promises, and open questions so nothing slips through the cracks. LINK
Inkling 2 Small: a flexible API for fine-tuning open source models with LoRA, giving researchers full control over data and algorithms without managing infrastructure. LINK
Higgsfield Miracle: edit video clips in real time by describing changes in plain language, applying precise edits without affecting the rest of the shot. LINK
Trending papers & reports
Elastic AI inference lets a language model decide on its own how much computing power each task needs and dial that down after training without retraining, cutting costs when speed or budget matters. LINK
Self-grading AI training lets models improve at reasoning by debating each other instead of relying on scarce answer keys, lifting accuracy by up to ~22 points across small models. LINK
Flex-RSI tests whether AI agents can rewrite their own tools and workflows to get better at vision and robotics tasks, finding self-improvement helps most when agents build solutions themselves and open models lag on strict correctness checks. LINK
Attention bottleneck fix speeds up the slowest step in how AI models weigh information, running up to ~3x faster on AMD chips and powering a video generator ~2x faster without hurting output quality. LINK
AI server retries can trap an overloaded model engine so it never recovers, with only 12-38% of calls getting through, and simply canceling abandoned work fails to fix it in any test. LINK
See you tomorrow for a new dose of ☕️ AIpresso!